We build what we use

Every agent needs three things: rules for what it may see and do, a runtime that does the work, and company knowledge it can trust. We built one open-source layer for each: an IAM layer for AI agents, an agent runtime and a corporate AI knowledge layer. They work on their own and fit together, and anyone can inspect them. We use them in our own processes too.

# config/agents/support-bot.yaml
agent: support-bot
owner: support-lead@example.com

roles:
  - zendesk:reader
  - jira:reader

# Explicit deny always wins.
deny:
  - "*:*:delete"
Myco

IAM layer for AI agents · open source

IAM for AI agents

Myco gives each agent one MCP endpoint with a reviewed set of tools for your SaaS apps. An agent sees only the tools and data its roles allow, acting for itself or on behalf of a signed-in person. Myco holds the vendor credentials, so agents never do, and it logs every decision.

  • Roles per agent and per user; explicit deny always wins
  • Rows scoped and sensitive fields redacted
  • Permissions as YAML in Git, deterministic decisions
github.com/vossmoos/myco →

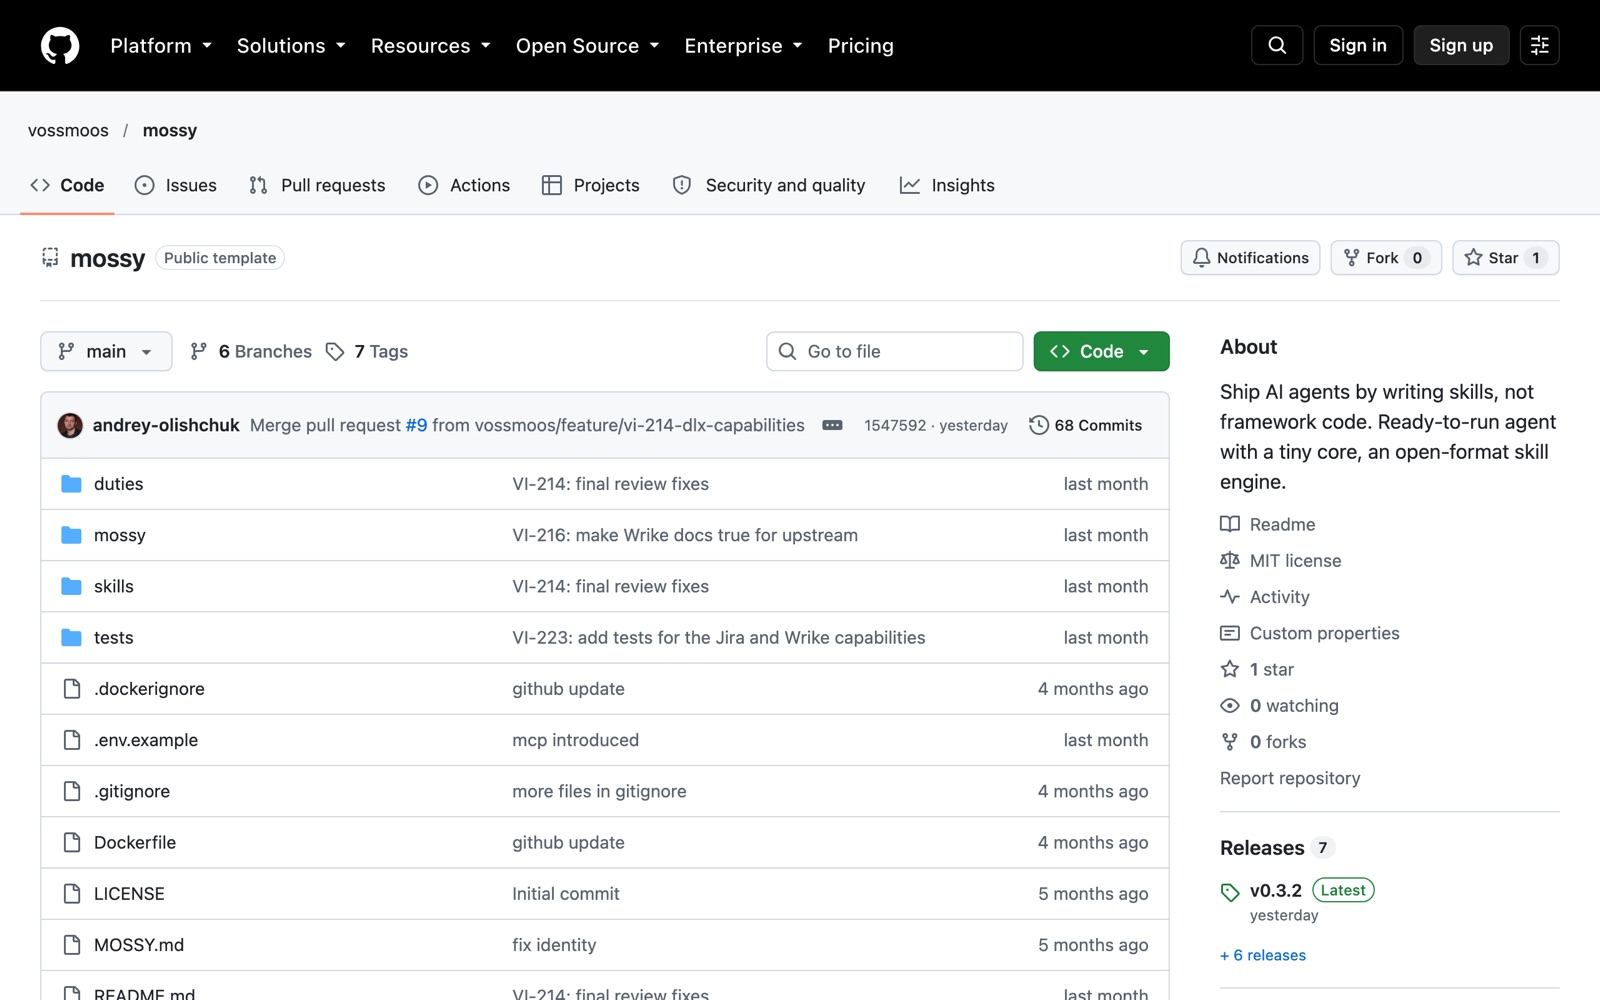
The Mossy repository on GitHub
Mossy

AI agent runtime · open source

Runs AI-operated work in production

Mossy is a skill-first runtime for operations that need more than one worker. New capabilities are added as skills rather than framework code, and work moves through channels and queues.

  • Composable workers and skills
  • Channels and queues
  • Reaches company tools through the IAM layer

github.com/vossmoos/mossy →

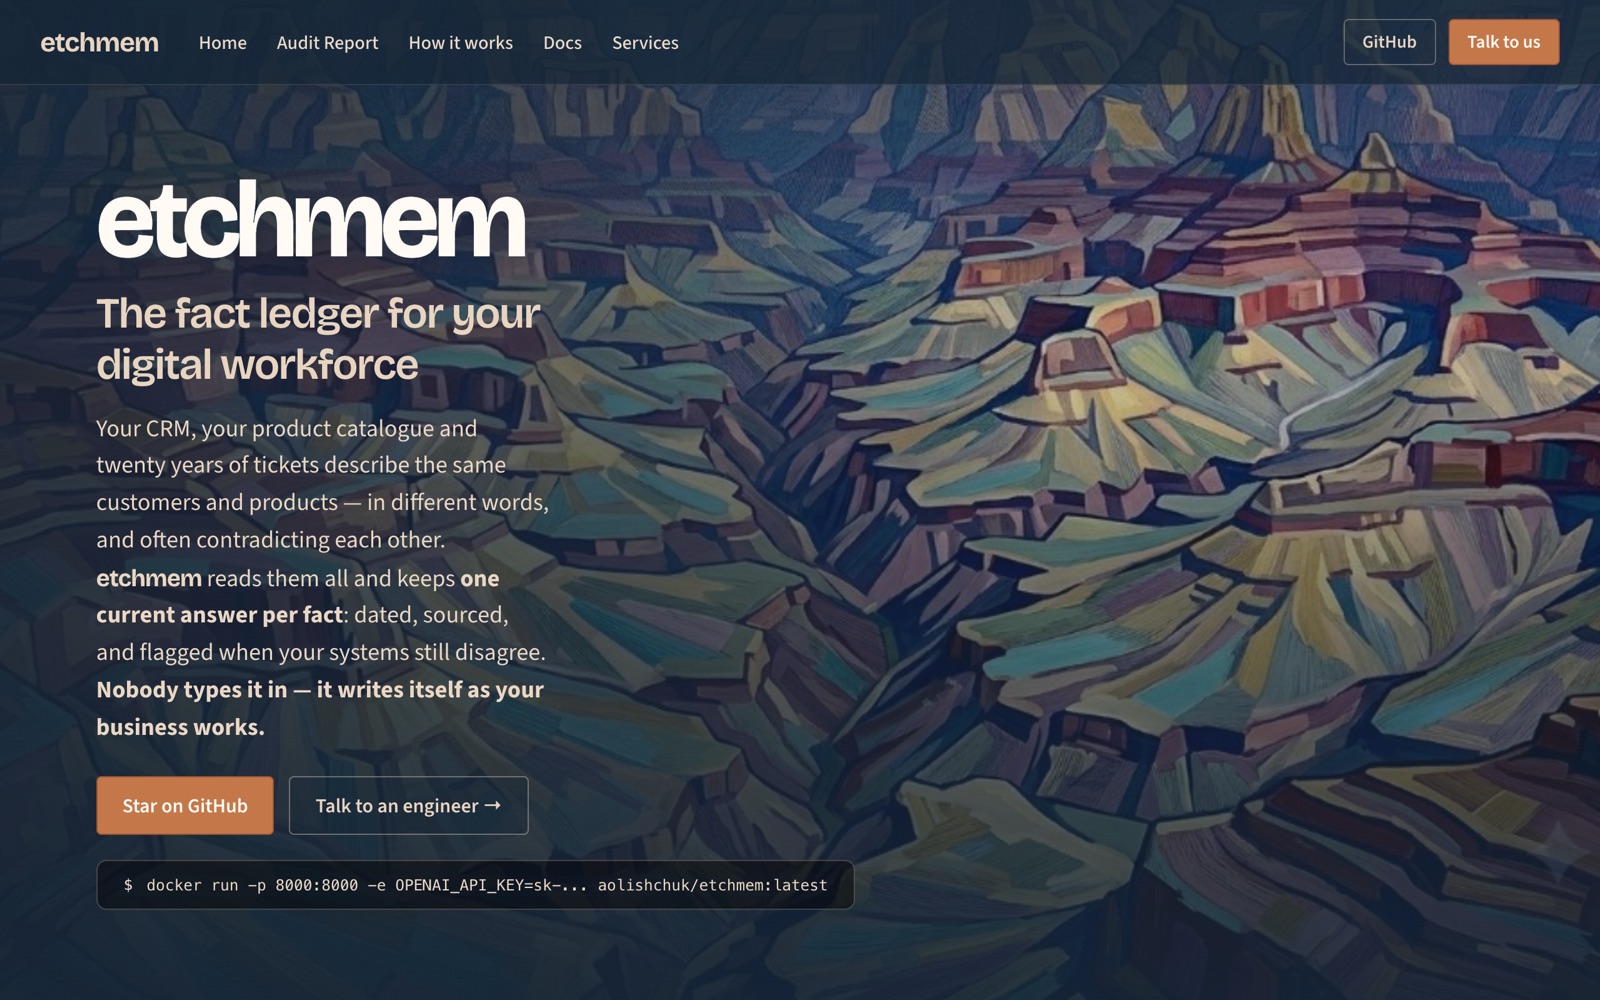
The EtchMem website
EtchMem

Corporate AI knowledge layer · open source

Knowledge every agent can trust

What one process learns or a colleague corrects becomes knowledge every process can use. EtchMem reads your CRM, product catalogue and ticket history, keeps one current answer per fact, dated and sourced, and flags where systems still disagree. It grows as the work happens, without anyone typing it in.

  • Learns from work and from corrections
  • Facts reconciled across systems
  • Sources and dates for every answer

etchmem.io →

Open datasets

Data we publish on Hugging Face

We also publish datasets from our engineering work, such as wind turbine SCADA readings and contactless soil sensing data, for anyone building and testing models on industrial and sensor data.

huggingface.co/vossmoos →

Getting started

Start with one agent

1Advise: we review the process or system with your team, set out the options and prepare the business case.
2Build: we engineer the solution end to end, from the connections to your systems to the infrastructure it runs on, and test it on cases your experts have signed off.
3Run: we operate and improve it, and review the results with you each quarter.
Schedule an introductory call